Hi there, we use cookies to ensure you get the best experience on our site.
Thank you! Your submission has been received!
Oops! Something went wrong while submitting the form.

A leading personal care manufacturer used a hybrid digital twin of its mixing process to run virtual experiments before committing to production equipment.
DoEs in personal care development take time and are reasource intensive.
Conditioners, creams, and lotions have to hit viscosity and particle size distribution (PSD) targets. Most teams rely on offline lab measurements and trial batches, which are slow, costly, and hard to repeat across product lines. During scale-up this becomes even more difficult as experiments to reach these targets at the new scale take time and consume resources.
High-throughput and low cost. Most of the program’s historical data lives here.
Give the team moment-in-time visibility into their viscosity and particle size distribution.
Model how viscosity and particle size develop through the batch.
Find the mixing speed and time that reach target viscosity and PSD.
Apply the model across formulations and equipment sizes.
Historian, ELN, and LIMS records in one dataset.
Historical mixing data from process historians, ELNs, and LIMS was merged into one dataset. The Data Labeler then marked the true start of mixing in every batch, using a signal that drops to zero when mixing begins.
Mixer speed, cooling profile, batch turnover
Oil phase, water phase, additives, physical properties
Mixer and impeller dimensions, geometry
A validated model was build and compared against historical data.
A population balance model (PBE) captures how droplets break up and coalesce under shear. It predicts how mixing speed, equipment geometry, and batch turnovers shape particle size distribution over time.
A machine learning model then maps the PSD metrics (d10, d50, d90, packing factor) to final viscosity. Together they link process conditions to product quality.
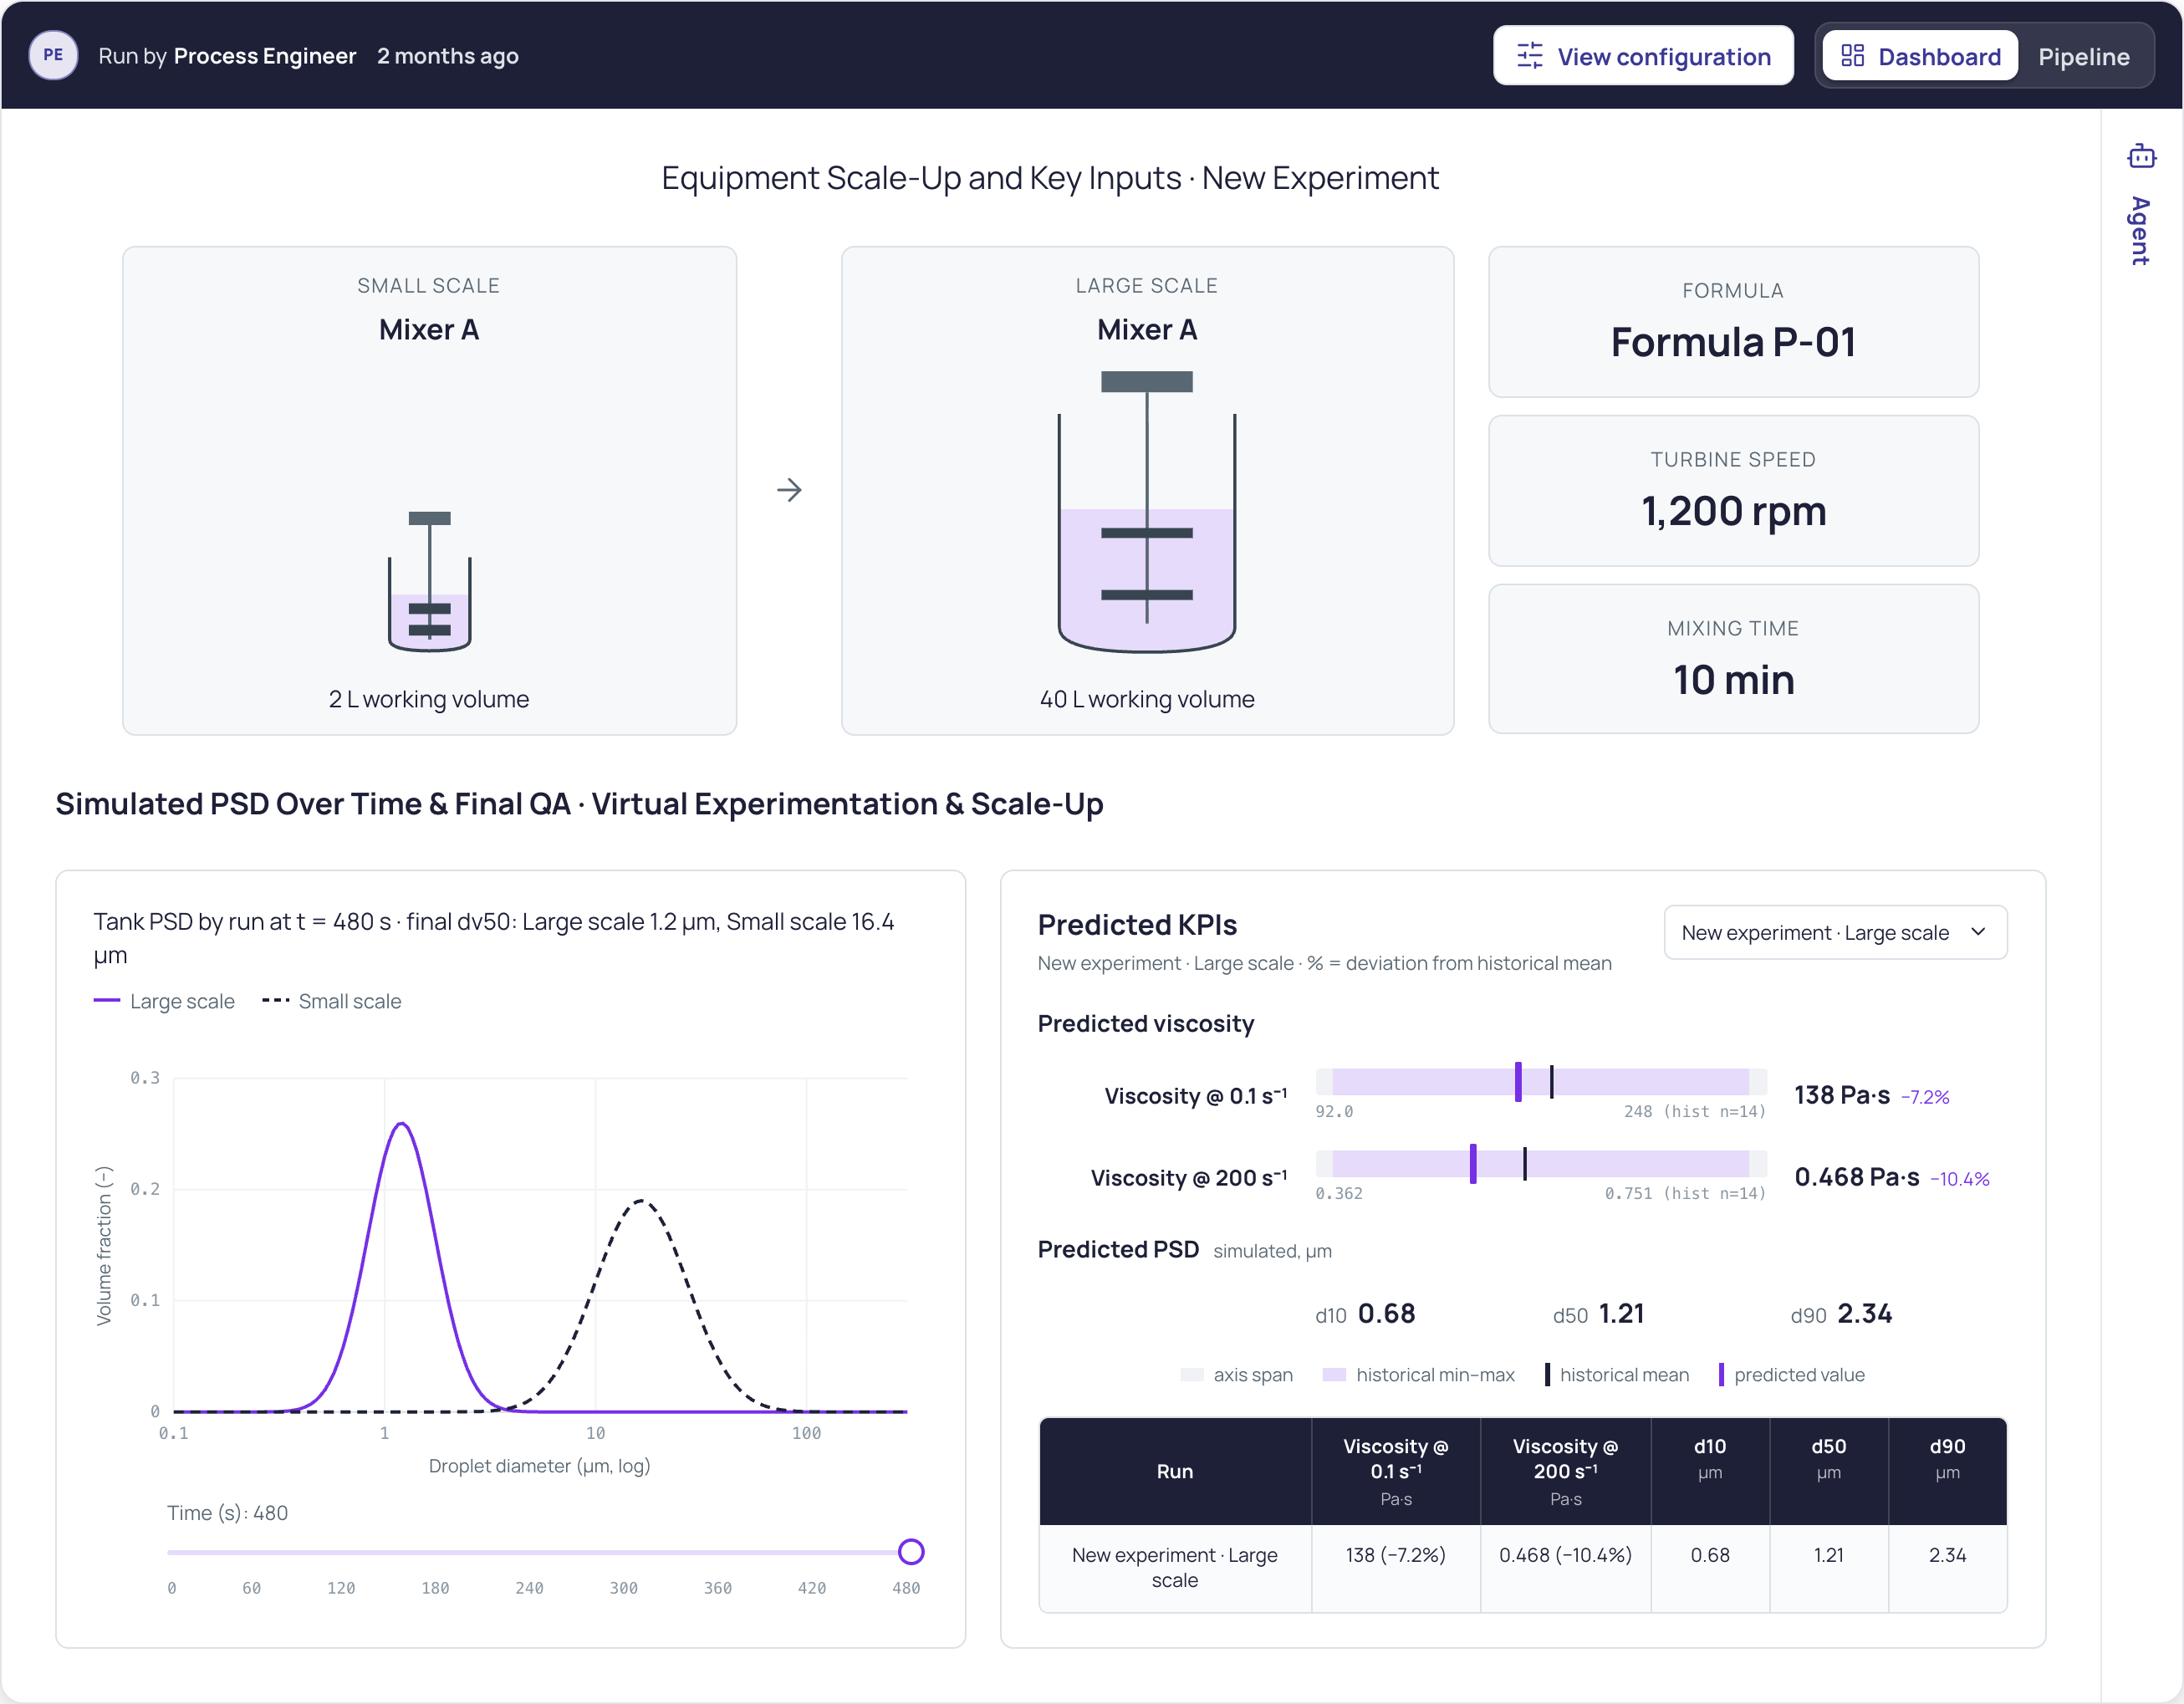
With the validated twin, the team tests mixing changes virtually before they reach production equipment. The result is accelerated scale-up timelines, reduced raw material consumption, and product reaching customers' hands faster.
The dashboard the team used, from process data to virtual scale-up.
The full case study covers the data schema, fitted parameters, validation results, and the sweep behind the 20% titer increase.
Process parameters (mixer speed, cooling profile, batch turnover), formulation data (oil phase, water phase, additives, physical properties), and equipment specs such as mixer and impeller geometry. In this use case it came from historians, ELNs, and LIMS.
Validated against historical batches, the hybrid digital twin was highly accurate, predicting key quality attributes with a mean absolute percentage error below 10%.
Instead of trial batches on production equipment, the experiments can be done virtually using a digital twin model that's validated against your historical data. It can measure the effects of your experiments on quality attributes like viscosity and PSD, virtually.
Yes, once you have a validated digital twin of your process you can use it to scale up across multiple formulations or equipments.
Every prediction is traceable to the dataset and parameters behind it, so results can be reviewed and documented within a QbD framework. Talk to us about your validation requirements.
